Can your SaaS product development company recover a failed release?
Can your SaaS product development company recover a failed release? Learn what to demand on rollback, data recovery and proof before shipping again.
Your latest release broke sign-in, left customer work unfinished or changed records it should have left alone. You need to know whether your SaaS product development company can restore a safe service, account for what happened to the data and give you evidence that the next release is safe to ship.
Recovery means more than getting the app to load again. It includes containing the damage, choosing a recovery path, checking affected customer work and putting a named person in charge. A company that can explain those steps clearly gives you something concrete to evaluate while the product is down.
Put one person in charge of recovery
For an early-stage SaaS without a technical owner, a failed release can turn the founder into a messenger between contractors. One person checks hosting, another blames a dependency and someone else waits for instructions.
Ask for one named engineer to own the recovery decision and coordinate the work. That person should maintain a short written record covering what is known, what is still uncertain, the current action and when you will receive the next update.
Google’s incident management guidance separates incident coordination, operational work and communication. Your company may not have separate people for those roles. The responsibilities still need an owner.
Your job is to decide business tradeoffs: whether to suspend a customer workflow, postpone a launch or accept a temporary restriction. The engineer should explain the technical consequences rather than ask you to choose between fixes you cannot evaluate.
An update should name the next decision and the evidence needed to make it. “We found an error” tells you little. “New submissions are paused while we check whether existing submissions were saved” tells you what is protected and what remains unresolved.
Your SaaS product development company should produce a recovery brief
Before approving another production change, ask for a short recovery brief. This can be a shared document, not a presentation. Its purpose is to keep everyone working from the same facts.
| Question | Evidence to request | Decision it supports |
|---|---|---|
| What changed? | The deployed version, relevant configuration changes and database changes | Whether the release caused the failure |
| Who or what is affected? | Known broken workflows, affected records and the limits of the investigation | What to pause and what to tell customers |
| What is the proposed recovery? | A rollback, targeted fix or restore plan with its risks | Whether to authorize the change |
| How will recovery be verified? | Checks against the failed workflow and affected data | Whether normal operation can resume |
The brief should distinguish confirmed facts from assumptions. “We have not found missing records” is different from “we checked every affected record and found none missing.”
Ask the company to preserve relevant logs and release information before routine cleanup removes them. If unauthorized access or data exposure is suspected, the work also needs security incident handling. A deployment fix alone cannot establish whether information was accessed.
You do not need a complete explanation before containing damage. You do need an explicit statement of what remains unknown.
Choose the recovery path before approving another deployment
A credible SaaS product development company should explain why its proposed recovery is safer than the alternatives. “We’ll push a fix” is incomplete if nobody has checked whether the previous version can still run or whether the release changed stored data.
Roll back when the previous version is still compatible
Returning to the last working application version can be appropriate when the failure is confined to code or configuration. It becomes more complicated if the release also changed the database, permissions or an external service.
Ask whether the old version can read and write the current data safely. A rollback that restores the screen but corrupts new records has created another incident.
Use a targeted fix when rollback would introduce more risk
Sometimes the safest path is a narrow correction to the current version. Require a bounded change with a test that reproduces the failure before the correction and passes afterward.
Keep unrelated improvements out of that release. A recovery deployment should be easy to explain and inspect, with a clear way to stop if it behaves unexpectedly.
Restore data only with a reconciliation plan
A backup restore can remove valid work completed after the backup was taken. Before authorizing it, ask what would be lost, whether affected data can be recovered separately and how the restored state will be checked.
Where feasible, the engineer should validate the restore in an isolated environment first. The existence of a backup does not prove it can restore the product to the state you need.
Check what happened while the release was broken
A failed release can leave work halfway through. A customer may have submitted a request that was saved but never processed. A background task may have retried. A confirmation email may have failed even though the underlying action succeeded.
Your SaaS product development company needs to account for those partial outcomes before declaring the incident closed.
Ask for a reconciliation record that states which actions completed, which failed and which remain uncertain. It should also identify the source used to verify each outcome, such as application records or the external service that actually performed the action.
Do not approve a blanket replay of failed tasks without checking for duplicates. Re-running a job can repeat an email, create another record or trigger an external action twice. The recovery plan must explain how completed work will be recognized and protected.
Customer communication should follow the same evidence. Tell affected customers what is known, what they should avoid doing and when they will hear more. Do not say their work is safe while the team is still determining whether it was saved.
If nobody can identify the affected records, record that limitation explicitly. Monitoring and reconciliation then become part of the follow-up work, rather than an assumption buried in the incident chat.
Accept recovery against the failed workflow
A successful deployment only proves that a release process completed. It does not prove that customers can finish the task that broke.
Require your SaaS product development company to demonstrate the original failure, the correction and the resulting state of the data. For a non-engineer founder, that evidence should be understandable without reading the code. A technical founder should also be able to inspect the change and its tests.
For example, if an invited user could not join an account, acceptance might require that the invitation reaches the intended recipient, the user joins the correct account and their permissions match the intended role. Testing an unrelated login screen would not cover that failure.
The check also needs a production observation period appropriate to the workflow. An immediate action and a background task that runs later require different evidence. Ask what signal would reopen the incident and who is watching it.
Do not require the founder to become the release tester by default. The engineer should assemble the evidence; the founder accepts the customer outcome and any remaining business restrictions.
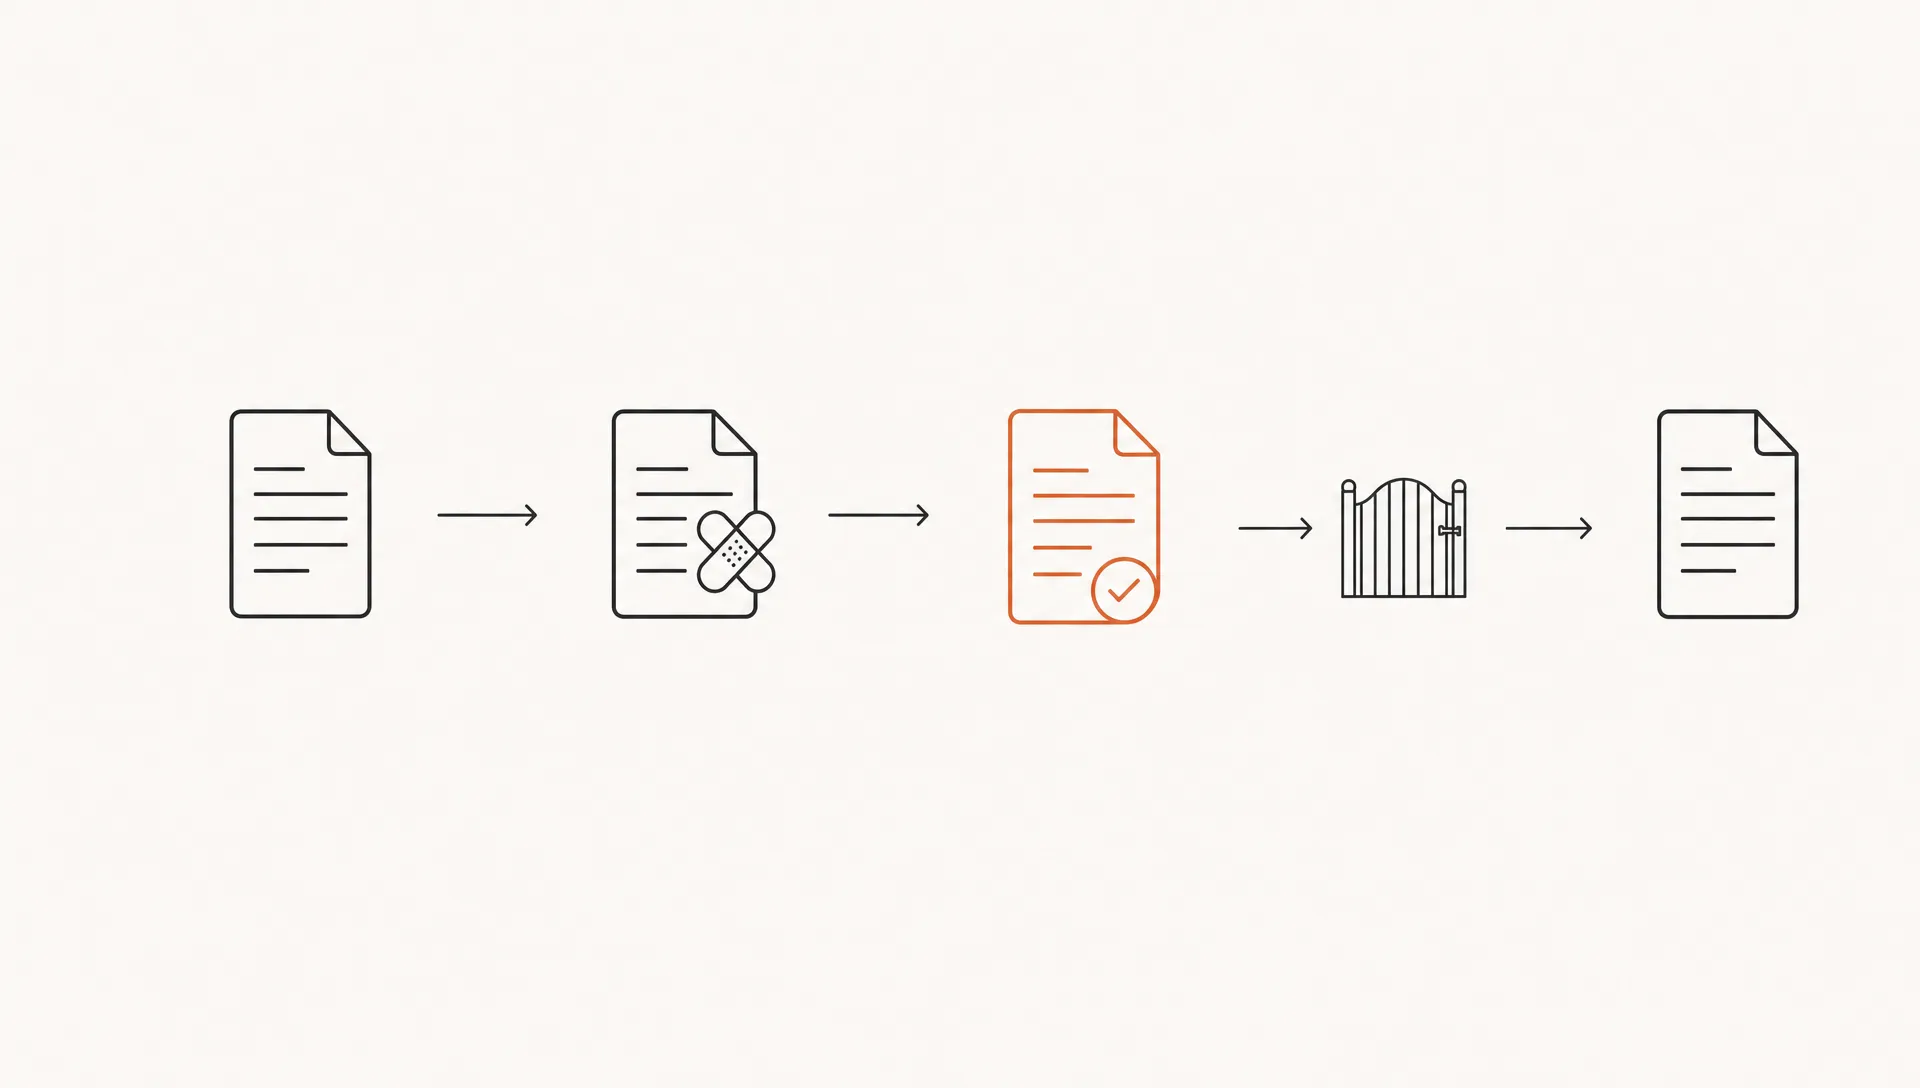
Use agentic engineering with a named engineer reviewing the work
Coding agents can inspect a codebase, propose a patch and write a regression test. Test, security and documentation agents can check the change from different angles. That can reduce manual work during recovery, but generated output still needs review.
In agentic engineering, one accountable engineer owns the technical judgment: what caused the failure, which change is appropriate and whether the evidence supports releasing it.
Ask your SaaS product development company where agents run, what information they can access and who authorizes production changes. Production credentials and sensitive customer data should not be handed to an agent merely because it can generate a plausible fix.
A useful division of responsibility is straightforward. Agents do the work. You make the decisions. The engineer remains responsible for reviewing implementation and explaining the decisions that need your approval.
For a founder who built a v1 with a coding agent, recovery is also a test of what is missing around the code. The missing piece may be a reproducible release process, useful logs or tests around the workflow that customers depend on. More generated code will not necessarily address those gaps.
Ask for those gaps to be named separately from the immediate repair. That keeps the urgent fix bounded while making the next piece of work visible.
Make the next release smaller and observable
After service is restored, request a short incident review. It should state what triggered the failure, why existing checks missed it and which specific changes will reduce the chance or impact of a repeat.
Avoid accepting “we need more testing” as the entire follow-up. Name the test, the workflow it protects and where it must pass before deployment. If the problem was a configuration change, adding unrelated application tests will not address the cause.
The next deliverable from your SaaS product development company should have a written definition of done. That might include the regression test, a verified recovery procedure and monitoring for the previously invisible failure.
Monitoring should follow customer work, not just whether a server responds. Depending on the product, useful signals could include failed submissions, stalled background tasks or mismatches between saved requests and completed actions. Usage and cost telemetry also matter if retries or repeated model calls can increase operating costs.
Choose a smaller release boundary where practical. Separating a database change from a new interface, or exposing a change to a limited group first, can make failures easier to isolate. Neither technique removes the need for recovery planning.
These are ongoing responsibilities. A clear agreement about what development services include after launch helps prevent them from disappearing once the urgent repair is accepted.
Decide whether the company can own the next release
A failed release alone does not tell you whether to replace the company. Its handling of the failure gives you more useful evidence.
Can it identify what changed? Does it distinguish confirmed facts from guesses? Does it protect data before attempting a destructive recovery? Can it show that the affected workflow works again?
Your SaaS product development company should leave the recovery record, code changes, tests and operating instructions in accounts your company controls. Your ability to recover should not depend on a contractor’s personal account or an explanation that exists only in a call recording.
Repeated unexplained fixes, missing release history or refusal to provide access are reasons to question the relationship. So is making you coordinate every technical decision without someone accepting responsibility for the whole recovery.
Changing providers during an incident has its own risk because the incoming engineer needs context. First secure company access, preserve the incident record and establish who is currently responsible. If access and ownership are already broken, use a bounded recovery plan after a bad developer handoff rather than commissioning an immediate rewrite.
A rewrite proposal should follow evidence about the existing product. It should not substitute for explaining why this release failed.
Frequently asked questions
Can a failed release always be rolled back? No. The previous application version may be incompatible with database changes or data written after deployment. The engineer needs to check compatibility before choosing rollback.
How long should recovery take? There is no reliable universal duration. Scope, data changes, access and the quality of recovery procedures all matter. Ask for the next checkpoint, the current uncertainty and what evidence is needed to choose the next action.
Should we replace our SaaS product development company after one failed release? Evaluate how it handles recovery before deciding. Named ownership, clear evidence and verified follow-up work support a different judgment from repeated guesses, hidden access or unexplained production changes.
Can agents recover the release without an engineer? They can propose changes and run checks within their permissions. A named engineer still needs to review the recovery path, protect production data and take responsibility for technical decisions.
Establish your recovery requirements this week
Write one page naming the recovery owner, the customer workflow you must protect, the evidence required to reopen it and where the recovery record will live. Confirm that your company controls the repository, hosting, database and relevant external service accounts. If the incident is still active, prioritize containment and recovery before expanding the roadmap.
Once service is stable, give the next accepted deliverable a written definition of done that addresses one gap exposed by the failure. Keep it specific enough that you can tell whether it shipped.
Archer Scaling AI helps early-stage SaaS become AI-native. We build and run the systems that develop, market and sell the SaaS so the founder’s time goes to the decisions. The AI-native assessment starts with seven days of read-only discovery across the company and codebase, ending in a written report and plan. The development retainer follows with one accepted deliverable each week, in the founder’s own repositories and accounts.
To discuss your company, the failed release and who should own what comes next, book a free intro call.